Bioinformatics
Bioinformatics
A 6-month, fully online postgraduate program that fuses core bioinformatics with hands-on applied AI — built and taught by scientists who have analyzed real genomic datasets, run real pipelines, and published real research.
This program page reflects our latest curriculum draft. Fees, faculty, and career-support details shown below are the ones on file in our admissions system — figures like guarantees or hiring-partner counts mentioned in course descriptions are illustrative and being finalized. Contact admissions for current details.
Why Bioinformatics, Why Now?
Genomic data is doubling every few months, and labs are drowning in sequences they can't interpret fast enough. The scientists who can pair biology with AI-driven analysis are the ones landing translational research and biotech roles.
Employers are increasingly screening for pipeline-literate scientists, AI-augmented variant analysis skills, cross-functional wet-to-dry-lab translators, and people who ship reproducible code — not just scripts.
- •3.2B+ base pairs per genome — data only AI-assisted pipelines can process at scale
- •45% faster variant analysis reported by teams using ML-assisted pipelines
- •60% of biotech job postings now list computational skills as required
- •2.5x more interview callbacks for candidates with a shipped pipeline project
The Gap Is Real
Across core bioinformatics roles, AI-assisted workflows are changing how the work actually gets done:
- •Genomics Researcher — from spending days manually inspecting alignment files and guessing at variant significance, to running automated QC pipelines that surface ML-flagged variants of interest instantly.
- •Lab Data Analyst — from building one-off scripts with no reproducibility between projects, to deploying versioned, containerized pipelines any teammate can rerun on new data.
- •Computational Biologist — from relying on static reference databases and manual literature search, to using AI-assisted annotation and predictive structural modeling to move from data to hypothesis in hours.
- •Clinical Genomics Specialist — from cross-referencing variant databases by hand against patient phenotypes, to using ML-ranked variant-phenotype matching to prioritize cases needing clinical review.
- •Proteomics Scientist — from waiting weeks for external labs to resolve protein structures, to predicting and visualizing candidate structures in-house within hours using deep-learning models.
Why Medivex AI?
- •Domain + AI, Together — every module (genomics, proteomics, structural biology) is taught with AI embedded from day one, so you learn to apply machine learning to real biological questions, not bolt it on afterward.
- •Taught by Practitioners — instruction comes from computational biologists who have built pipelines used in real research labs and biotech companies.
- •Hands-On, No Theory Theatrics — you align sequences, build pipelines, train models, and analyze real -omics datasets, delivering outputs that look like real lab work.
- •Real Datasets, Real Problems — you work with real, messy genomic and clinical datasets modeled on academic and biotech research, not tidy textbook FASTA files.
- •Reproducibility Built In — every capstone requires a containerized, version-controlled pipeline, so you graduate already working the way modern research labs expect.
- •Cohort-Based Accountability — weekly live sessions and peer pipeline reviews keep you shipping on schedule instead of stalling out on a self-paced course.
Traditional vs. Medivex AI
- •AI & Domain — Traditional: taught as separate electives. Medivex AI: embedded in every module.
- •Faculty — Traditional: primarily academic. Medivex AI: practitioners who've shipped it.
- •Assessment — Traditional: essays & written exams. Medivex AI: shipped pipelines & live capstones.
- •Format — Traditional: fixed campus schedule. Medivex AI: 100% online, fits your job.
- •Cohort Size — Traditional: 200+ students, one-size-fits-all. Medivex AI: small live cohorts with direct faculty access (~1:12).
- •Tooling — Traditional: legacy academic software. Medivex AI: production tools — GATK, Nextflow, AlphaFold, AWS.
Choosing Your Specialisation Track
Most learners don't lock in a track on day one — they spend week one sampling all three, then choose based on the roles they're actually targeting.
How We Pick Our People
- •Shortlist Call — a quick conversation to understand your goals and alignment with the program.
- •Aptitude Test — a brief assessment of your domain thinking and analytical sharpness.
- •Interview — a deeper evaluation of your ambition, intent, and readiness to grow.
- •Offer Rollout — if the fit is clear, an invitation to join the cohort.
Program Details
- •Format: 6 months, 100% online, live cohorts, sessions recorded for later.
- •Cohort size: small live cohorts, roughly a 1:12 faculty-to-learner ratio.
- •Eligibility: bachelor's degree in any related discipline; open to graduates and professionals in life sciences, biotechnology, or a related quantitative field.
- •Admissions: Shortlist call → Aptitude test → Interview → Offer rollout.
- •Career support: AI-powered mock interviews, resume & profile workshops, 1:1 career strategy calls, curated peer community, job-search accountability pods.
- •Certification: verifiable digital certificate and shareable credential for LinkedIn and resume upon completion.
Curriculum Outline
Click any row to expand detailsMolecular biology fundamentals, Python & R for life sciences, sequence alignment, and public databases (NCBI, Ensembl) — the core toolkit every computational biologist needs. (The week-by-week breakdown below spans the first 12 weeks of Phase 1.)
Key Topics & Modules
Process a raw sequencing dataset, run QC, align reads, call variants, and present findings the way a real wet-lab-to-dry-lab handoff works.
Key Topics & Modules
Identify high-impact ML opportunities, design predictive models, and interpret results responsibly.
Key Topics & Modules
Genomics & Variant Analysis / Structural Bioinformatics / Clinical & Translational.
Design and build an AI-powered bioinformatics pipeline end-to-end, presented to an industry panel.
Key Topics & Modules
Week-by-Week Breakdown
Core genetics and gene-expression concepts, framed for computational analysis.
Reproducible scientific computing for sequence and genomic data.
BLAST fundamentals and pairwise alignment algorithms.
Multiple sequence alignment and phylogenetics basics.
Navigating NCBI, Ensembl, UCSC, and public sequencing repositories.
Hypothesis testing and experimental design for high-dimensional biological data.
FASTQ, BAM, VCF — reading and manipulating raw sequencing output.
Automated QC for whole-genome and whole-exome sequencing data.
Statistical genomics workflows using the Bioconductor ecosystem.
Build a first-pass sequence alignment pipeline end-to-end.
Iterate, validate, and document your pipeline for review.
Consolidate learning and prep for the Mini Capstone.
Specialisation Tracks
Genomics & Variant Analysis
Master end-to-end variant discovery, from raw reads to clinically actionable calls. Skills covered: variant calling, annotation, cohort analysis, ML scoring.
Structural Bioinformatics
Predict and analyze protein structure and function using AI-driven modeling tools. Skills covered: structure prediction, docking, visualization, drug-target analysis.
Clinical & Translational
Bridge bench research and the clinic by connecting genomic findings to patient outcomes. Skills covered: phenotype matching, reporting, regulatory basics, cohort studies.
Tools & Technologies
Gain hands-on proficiency with the actual software, platforms, databases, and computational frameworks standard across leading healthcare and research organizations.


Capstone Projects
Apply your learning to end-to-end, industry-standard portfolio projects modeled on real-world pharmaceutical, clinical, and health-tech workflows.
Whole-Exome Sequencing (WES) Variant Calling Pipeline
Construct an automated, containerized GATK/Nextflow pipeline for high-throughput germline and somatic variant discovery.
RNA-Seq Differential Gene Expression Analysis
Perform end-to-end transcriptomic profiling, DESeq2 differential expression, and pathway enrichment on cancer datasets.
AI-Powered Protein Structure Prediction & Docking
Utilize AlphaFold models and AutoDock Vina to predict 3D protein conformers and simulate small-molecule binding affinities.
Single-Cell Transcriptomics & Cell Type Clustering
Process single-cell RNA-seq (scRNA-seq) datasets with Seurat/Scanpy for cell subtype classification and marker discovery.
Program Faculty
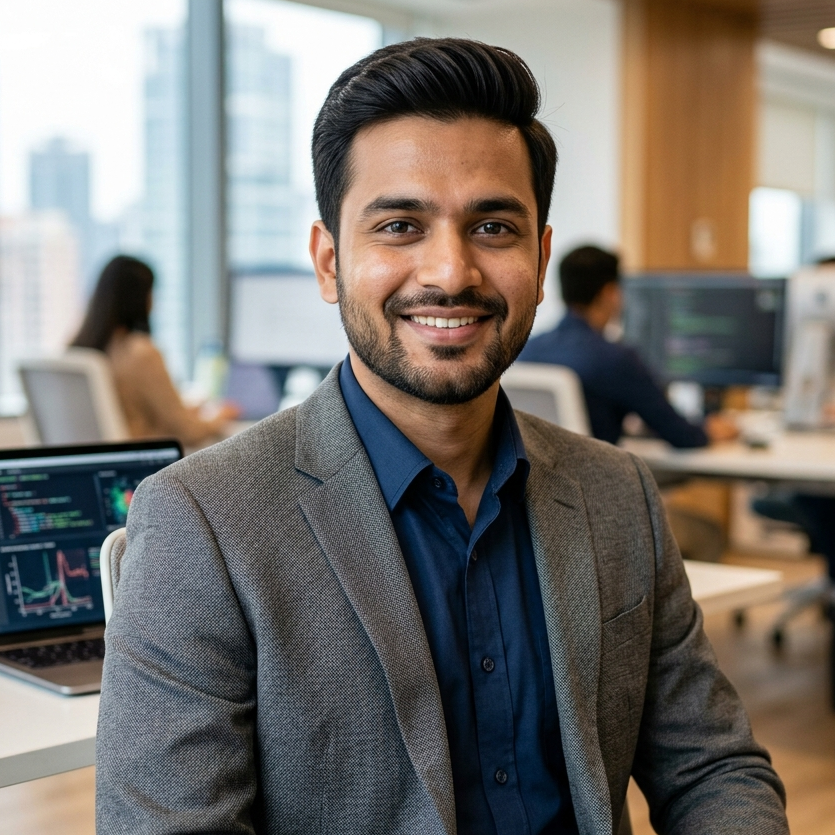
Arjun Rao
Faculty, Bioinformatics
Arjun Rao brings 8+ years of industry and teaching experience in Genomics & NGS Analysis.
Career Opportunities
Program Cohorts
Join a structured, mentor-led cohort focusing on NGS data pipelines, genomic data analysis, Python/R, and AI-driven structural biology.
6 Months
Live Online Classes
Live Regular classes on Saturday & Sunday (Choose either 10:00 AM - 12:00 PM or 7:00 PM - 10:00 PM)
Monday to Friday round-the-clock mentor assistance
Strictly capped at 10 students per batch for personalized attention
What You'll Get
- ✓AI-powered mock interviews
- ✓Resume & profile workshops
- ✓Executive presence sessions
- ✓Mentorship from experienced researchers
- ✓Curated peer community
- ✓Industry mixers & lab connects
- ✓1:1 career strategy calls
- ✓Job-search accountability pods
- ✓Build reproducible genomic pipelines
- ✓Apply ML to variant & expression data
- ✓Communicate findings with clarity
- ✓Navigate research data ethics
- ✓Bridge wet-lab and computational teams
- ✓Present research-grade reports
- ✓Predict and validate protein structures
- ✓Career pathways: Computational Biologist, Bioinformatics Scientist, Genomics Data Analyst, Research Pipeline Engineer, Clinical Genomics Specialist, Biotech Founder / R&D Lead
Who This Is For
- •Life Science Graduates & Researchers — biology, biotech, or life-sciences graduates and early-career researchers wanting computational fluency.
- •Working Bioinformaticians & Lab Scientists — professionals in genomics, pharma, or diagnostics labs looking to add AI/ML to their pipeline toolkit.
- •Eligibility: open to graduates and professionals with a background in life sciences, biotechnology, or a related quantitative field. A bachelor's degree in any related discipline is required.
- •What we look for beyond the resume: ambition, ownership mindset, curiosity about AI, consistency under pressure, and coachability.
Frequently Asked Questions
Success Stories
Hear from our alumni who have successfully transitioned into rewarding Medivex AI careers.
Ready to start Bioinformatics?
Talk to admissions or download the full brochure to see the complete curriculum.